Full list

Publications

01
Research Area

LLM & Agentic AI

1 Paper
Cross-Domain Hybrid OPD for Generalizable Search Agents thumbnail
Technical Report2026
Hongzhan Chen, Xiaoyu Liu, Dengming Zhang, Minzhou Huang, Dongliang Xu, Jingcheng Xie, Dongxiang Fang, Bowen Qin, Minsheng Hao, Yaozong Shen, Xiaojun Quan, Mona Zhou, Haosheng Zou, Jeff Chen
Motivation
Search-oriented RL improves retrieval but can erode the general reasoning and instruction-following skills expected from universal assistants.
Method
Hybrid-OPD couples agentic search RL with cross-domain expert distillation, preserving search specialization while recovering broad capabilities.
02
Research Area

Multimodal Large Models

3 Papers
Expert Merging: Model Merging with Unsupervised Expert Alignment and Importance-Guided Layer Chunking thumbnail
ICLR 26
International Conference on Learning Representations (ICLR)2026
Dengming Zhang, Xiaowen Ma, Zhenliang Ni, Zhenkai Wu, Han Shu, Xin Jiang, Xinghao Chen
Motivation
Existing model-merging methods rely on hand-tuned weights and treat every layer alike despite large differences in layer importance.
Method
Expert Merging learns layer-wise coefficients from unlabeled calibration data and assigns finer merging granularity to high-impact layers.
Learning to Hear by Seeing: It's Time for Vision Language Models to Understand Artistic Emotion from Sight and Sound thumbnail
Preprint2025
Dengming Zhang, Weitao You, Jingxiong Li, Weishen Lin, Wenda Shi, Xue Zhao, Heda Zuo, Junxian Wu, Lingyun Sun
Motivation
Artistic emotion emerges from sight and sound together, but most audio-visual models depend on expensive, large-scale audio pretraining.
Method
VAEmotionLLM aligns a new audio pathway to visual signals, then uses a lightweight adapter to learn cross-modal emotion.
VLM-Pruner: Buffering for Spatial Sparsity in an Efficient VLM Centrifugal Token Pruning Paradigm thumbnail
CVPR 26
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)2026
Zhenkai Wu, Xiaowen Ma, Zhenliang Ni, Dengming Zhang, Han Shu, Xin Jiang, Xinghao Chen
Motivation
VLMs process many redundant visual tokens, while importance-only pruning can retain duplicates and miss critical image regions.
Method
VLM-Pruner balances redundancy and spatial coverage through centrifugal selection, spatial-sparsity buffering, and selective token fusion.
03
Research Area

Affective Computing & Music Emotion

1 Paper
Personalized Dynamic Music Emotion Recognition with Dual-Scale Attention-Based Meta-Learning thumbnail
AAAI 25
Proceedings of the AAAI Conference on Artificial Intelligence (AAAI)2025
Dengming Zhang, Weitao You, Ziheng Liu, Lingyun Sun, Pei Chen
Motivation
Dynamic music emotion changes over time and across listeners, yet existing models capture neither long-range context nor personal perception well.
Method
DSAML combines dual-scale attention with annotator-specific meta-learning to personalize emotion prediction from a single user annotation.
04
Research Area

Meta-learning & Diagnosis

1 Paper
Few-shot bearing fault diagnosis based on meta-learning with discriminant space optimization thumbnail
MST 22
Measurement Science and Technology2022
Dengming Zhang, Kai Zheng, Yin Bai, Dengke Yao, Dewei Yang, Shaowang Wang
Motivation
Real-world bearing faults provide few labeled examples and appear under heavy noise and shifting operating conditions.
Method
MLDSO optimizes a discriminative, fault-tolerant feature space for meta-learning, enabling robust diagnosis from only a few samples.
05
Research Area

Controllable Generation & Creative AI

6 Papers
StyleFactory: Towards Better Style Alignment in Image Creation through Style-Strength-Based Control and Evaluation thumbnail
UIST 24
Proceedings of the 37th Annual ACM Symposium on User Interface Software and Technology (UIST)2024
Mingxu Zhou, Dengming Zhang, Weitao You, Ziqi Yu, Yifei Wu, Chenghao Pan, Huiting Liu, Tianyu Lao, Pei Chen
Motivation
People and image generators often disagree on what a style means and how strongly it should appear.
Method
StyleFactory turns style strength into an interactive ranking and visualization workflow for iteratively aligning personal style.
FonTS: Text Rendering with Typography and Style Controls thumbnail
ICCV 25
International Conference on Computer Vision (ICCV)2025
Wenda Shi, Yiren Song, Dengming Zhang, Jiaming Liu, Xingxing Zou
Motivation
Text-to-image models struggle to keep fonts and styles consistent or apply typography to specific words.
Method
FonTS pairs parameter-efficient typography tuning with control tokens and a text-agnostic adapter for precise type and style control.
Controllable Video-to-Music Generation with Multiple Time-Varying Conditions thumbnail
ACM MM 25(Oral)
33rd ACM International Conference on Multimedia (ACM MM)2025
Junxian Wu, Weitao You, Heda Zuo, Dengming Zhang, Pei Chen, Lingyun Sun
Motivation
Video-to-music systems often generate in a black box, giving users little control over musical attributes that evolve over time.
Method
The framework combines temporal alignment, dynamic condition fusion, and guided decoding to follow multiple time-varying controls.
Spatial-Temporal Decomposition and Alignment in Controllable Video-to-Music Generation thumbnail
ACM MM 25
33rd ACM International Conference on Multimedia (ACM MM)2025
Weitao You, Heda Zuo, Junxian Wu, Dengming Zhang, Zhibin Zhou, Lingyun Sun
Motivation
Most video-to-music methods prioritize output quality but make the generated music difficult to adapt to user intent.
Method
The model decomposes and aligns spatial-temporal video-music features through flow matching, enabling flexible control without explicit labels.
WordCon: Word-level Typography Control in Scene Text Rendering thumbnail
Under Review2025
Wenda Shi, Yiren Song, Zihan Rao, Dengming Zhang, Jiaming Liu, Xingxing Zou
Motivation
Scene-text models frequently apply typographic attributes to the wrong words because text tokens and image regions are misaligned.
Method
WordCon uses text-image grounding, hybrid parameter-efficient fine-tuning, and region-aware losses for precise, portable word-level typography control.
Aligning AI Capabilities with Pattern Design: An Intelligent Design Assistant based on Language Agents thumbnail
Under Review2024

Aligning AI Capabilities with Pattern Design: An Intelligent Design Assistant based on Language Agents

Dengming Zhang, Wenda Shi, Yufan Xi, Heyang Yi, Weitao You, Nan Li, Li Zhang, Xin Yao, Xiangdong Li, Lingyun Sun
Motivation
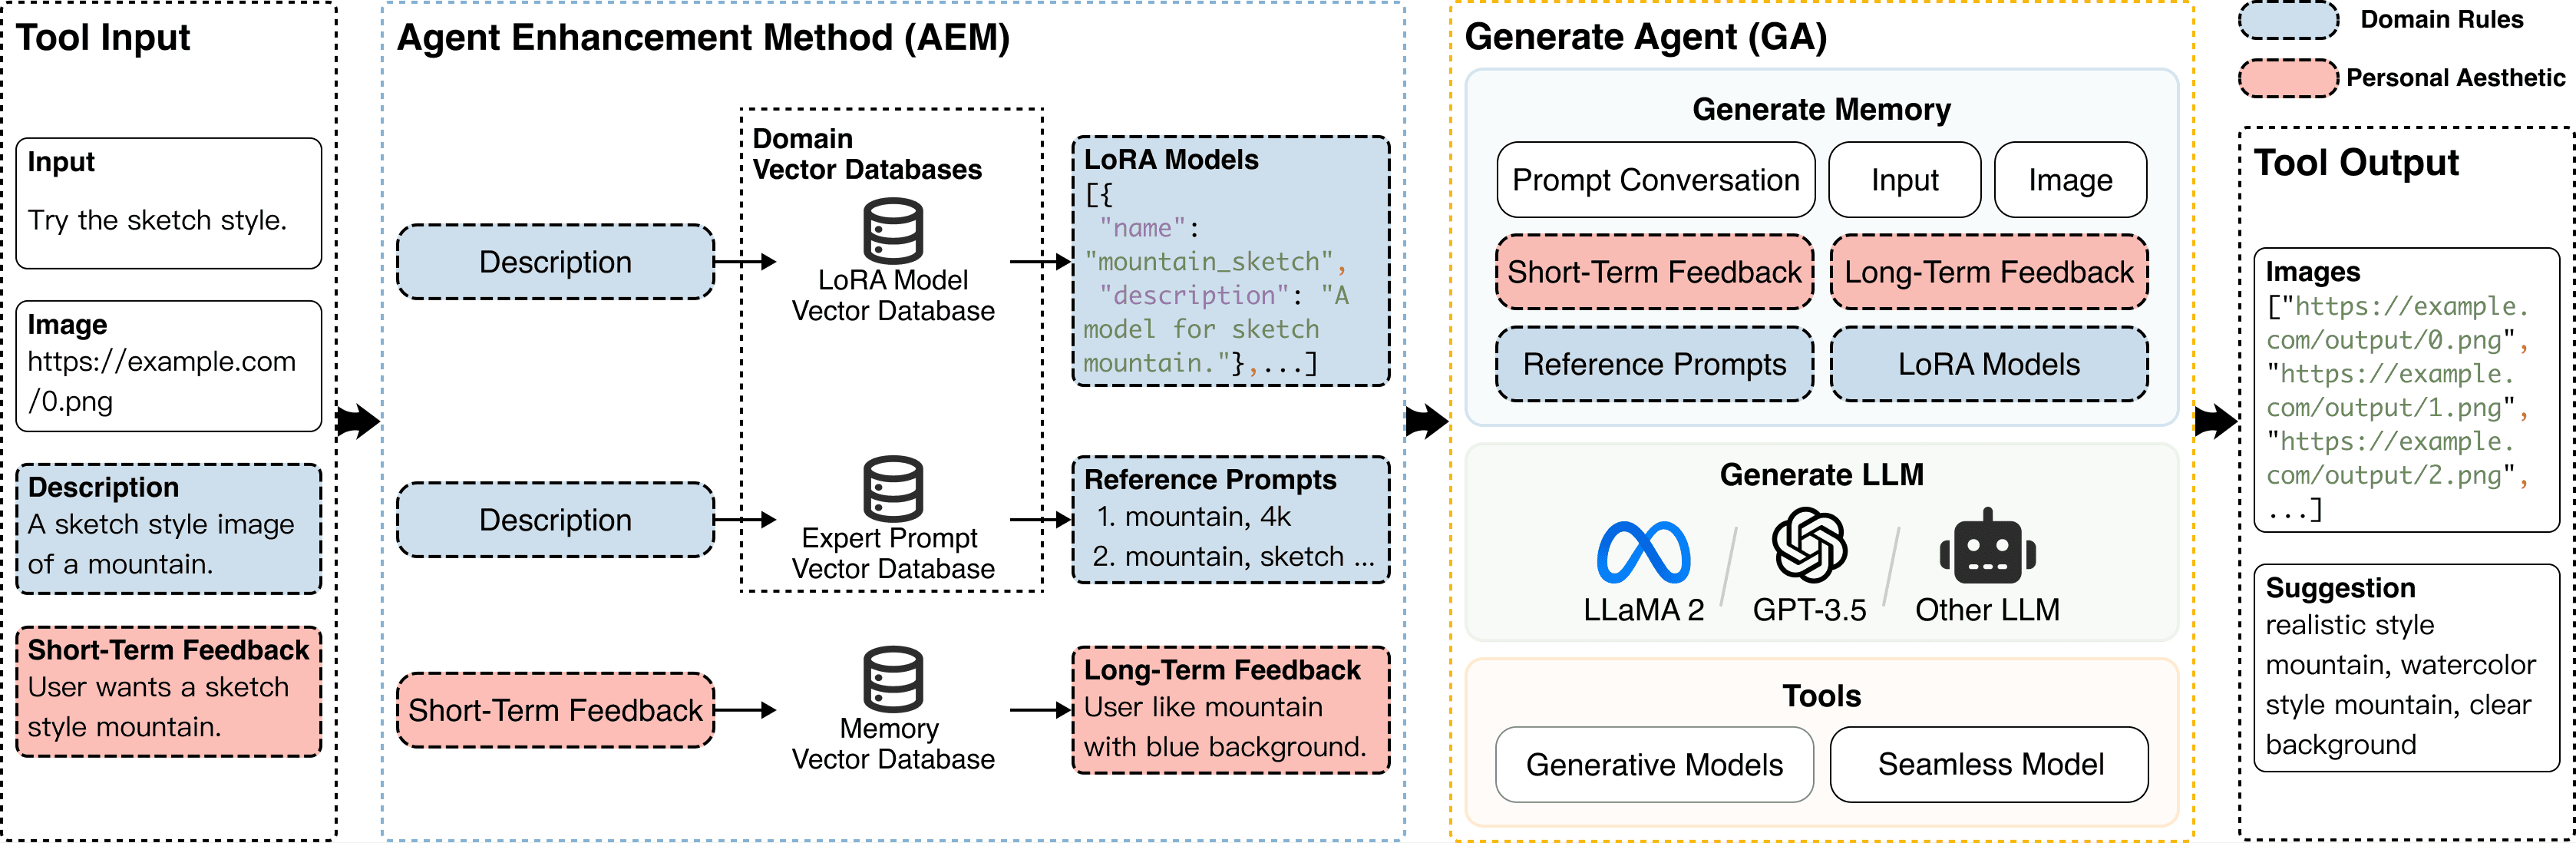
Generic language agents do not naturally fit the goals, terminology, and iterative workflow of professional pattern design.
Method
Patternista maps agent capabilities onto pattern-design tasks to provide a more intuitive, workflow-aligned creative assistant.

Patents

  1. Controllable front-end and back-end secure communication method

    Dengming Zhang, Shaowang Wang
    CN112311531B • Invention PatentGranted
  2. A personalized music dynamic emotion recognition method and device

    Weitao You, Dengming Zhang, Mingxu Zhou, Heda Zuo, Pei Chen, Tianyu Lao
    CN119128692B • Invention PatentGranted
  3. A long text writing method and device based on a large memory natural language model

    Dengming Zhang, Heyang Yi, Lingyun Sun, Dong Mei
    CN118606460A • Invention Patent
  4. Clothing pattern design system and method based on natural language dialogue

    Dengming Zhang, Heyang Yi, Lingyun Sun, Dong Mei
    CN118071885A • Invention Patent
  5. Method and device for quickly previewing patterned garments

    Heyang Yi, Dengming Zhang, Lingyun Sun, Dong Mei
    CN118710777A • Invention Patent